The AI Hardware I Own: ASUS Ascent GX10, a Mac mini and a MacBook Pro
I run AI on hardware I own. Three machines. One ASUS Ascent GX10, one Mac mini and one MacBook Pro. That's the whole stack.
4 min read Nov 2, 2026
14 articles share this tag.
I run AI on hardware I own. Three machines. One ASUS Ascent GX10, one Mac mini and one MacBook Pro. That's the whole stack.
Nex AGI posted Nex-N2.5-mini under Apache 2.0. Official BF16 usedStorage is 70.24 GB of weights. Sep 9 fold: mradermacher GGUFs are real, Q2_K through Q8_0, 12.94 to 36.90 GB. All fit a GX10 as a file-size claim. Official serve is patched SGLang on 2×H100. I have not loaded it.
ggml-org tagged llama.cpp v0.4.0 on Sep 4, 2026. Nightly on that release is b10809. ggml is bumped to v0.23.0. This is a changelog note, not a GX10 sit.
Official FP8 and NVFP4 fit 128GB on disk. llama.cpp PR 28323 merged; first nightly with the expert-layer fix is b10796. I have not loaded this on the GX10. Not a sit.
IFM posted K2 Horizon under Apache 2.0: six sizes from 0.9B to 375B-A23B. Official under-~110 GB GGUF/FP8 siblings fit on paper. 375B FP8 does not. Not a bench. Not a GX10 load.
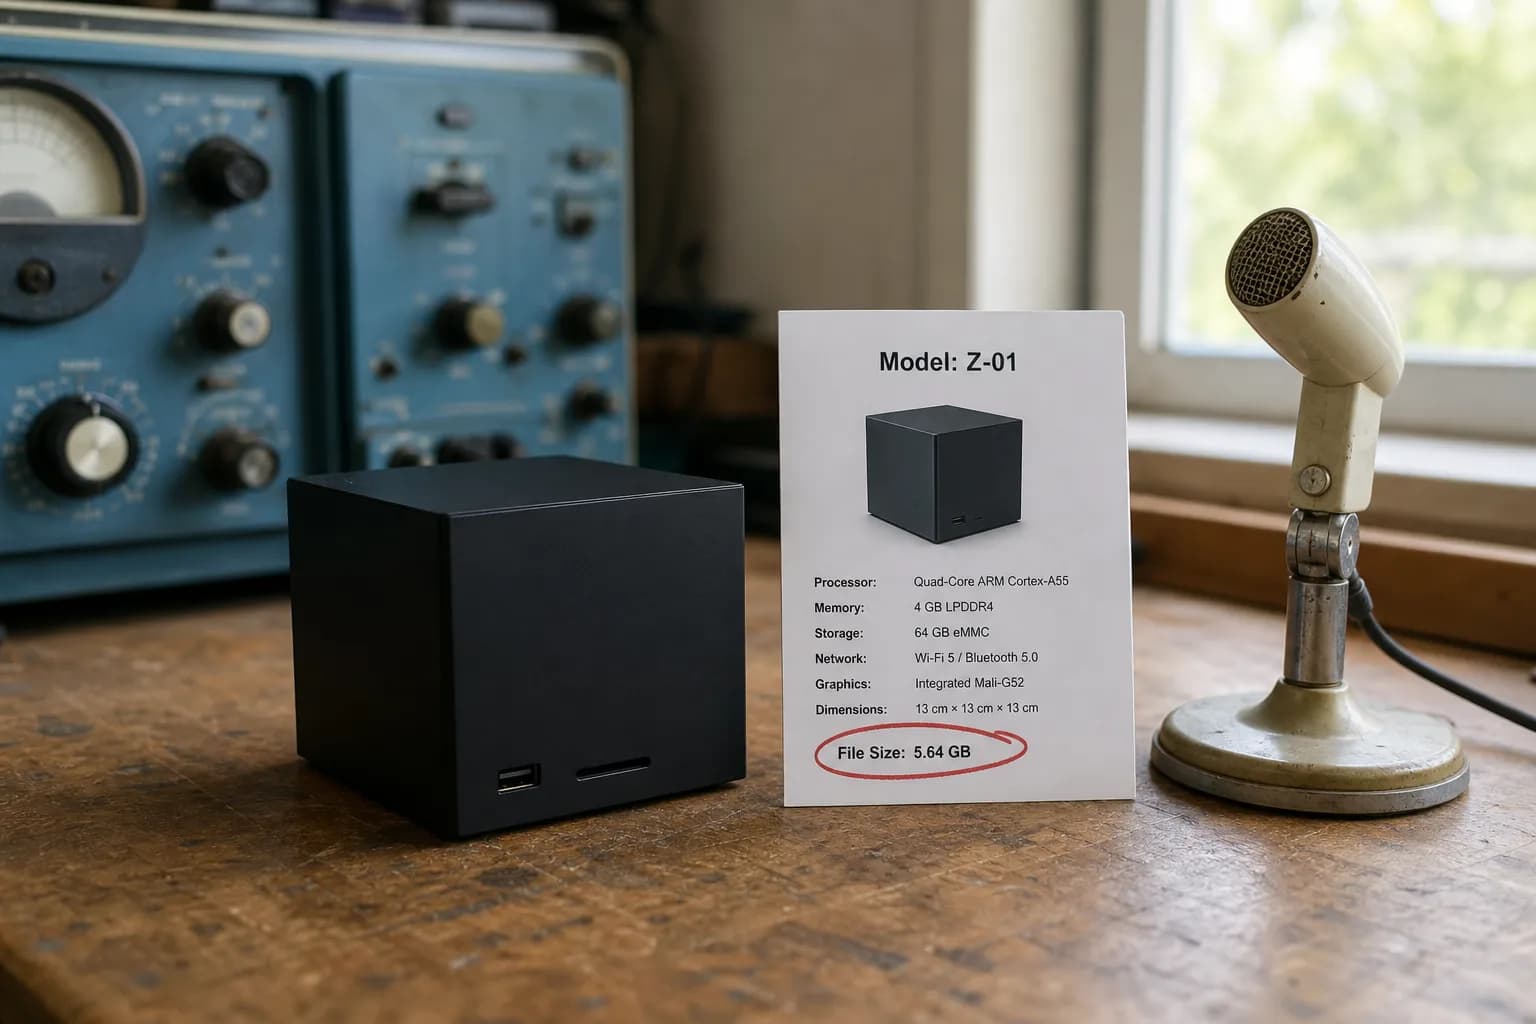
Microsoft posted streaming ASR weights today: 1.5B usedStorage 5.64 GB, 7B 17.35 GB. MIT. Both fit a GX10 as a file-size claim. This is not TTS, and I have not loaded it.
AngelSlim posted Hy4-preview GGUFs. Smallest card size is 213.66 GiB. Still not a GX10 sit. Stock llama.cpp does not run them.
XHToken posted Spark-X2.5 4B and 1.7B under Apache 2.0. Official 4B BF16 is 8.23 GB of weights. That fits a GX10. Native 1M is claimed. I have not timed it, and this is not NVIDIA Spark.
Unsloth IQ1_S is 82.44 GB. ggml-org Q2_K_S is 98.59 GB. llama.cpp b10762 has PR 28133. Still not a GX10 sit.
Tencent posted Hy4-preview on Aug 28: 770B / 49B active, Apache 2.0. Official usedStorage is 1.56 TB. Official FP8 is 814 GB. No public GGUF. Not a GX10 sit.
Qwen posted Flash-Next on Aug 26: 125B / 6B active, plus 51B n-gram and 4B MTP. Official BF16 is 360 GB. Unsloth GGUFs landed; the smallest is 72.5 GB and still not a GX10 sit.
Open WebUI tagged v0.11.1 on Aug 25. Admins can pause each tool call for allow or deny. Automations and temp chats stay out. Their 1000x stream claim is theirs.
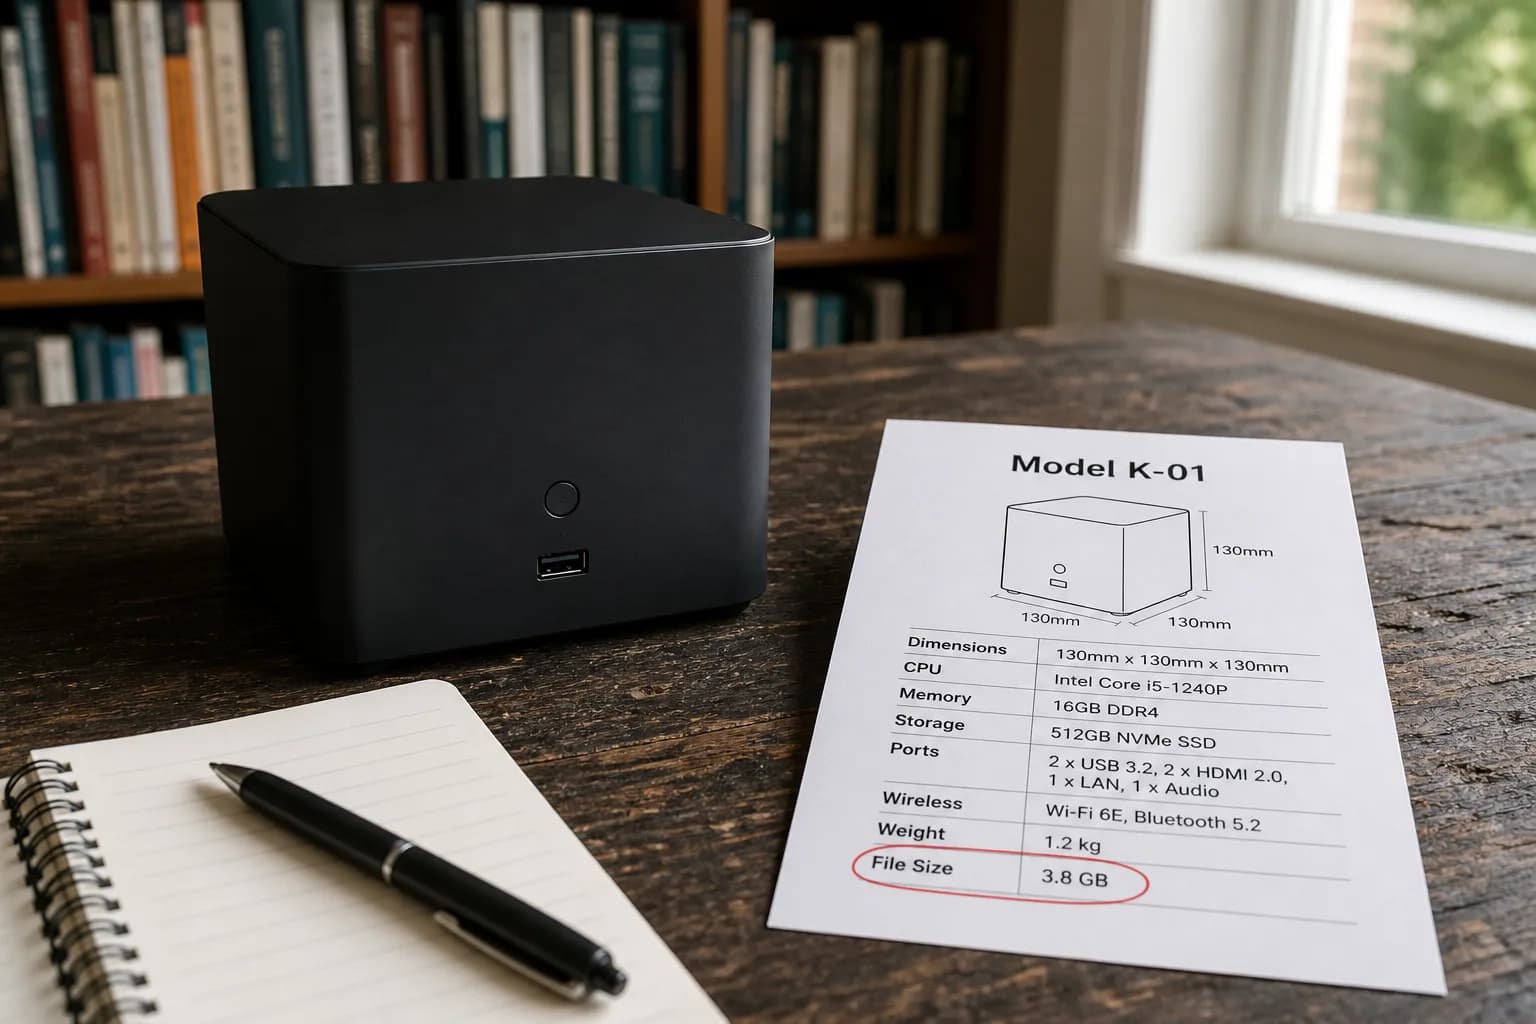
IBM posted Granite 4.2 on Aug 25: Apache 2.0, dense 3B/8B/30B, thinking switch, 128K native. Official 30B BF16 is 58.55 GB of weights. That fits a GX10. I have not timed it.
ggml-org tagged llama.cpp v0.3.0 on Aug 25. It adds dots3-note, GLM-4.5-Air MTP, DeepSeek 4 -sm tensor, and a moov-at-EOF video fix. A GitHub tag is not a GX10 number.