Disclosure: As an Amazon Associate I earn from qualifying purchases. This site contains affiliate links.
The Local Models I Actually Run on My GX10

Local LLMs on NVIDIA Spark / ASUS GX10
People ask what I run locally. Here's the list, straight from my run logs. Every model here ran on my GX10.
No scores in this post. If you want numbers, the board is at wikiwayne.com/wikibench.
Why local models on a GX10
The GX10 has 128GB of memory and the NVIDIA GB10. That's enough room for small models at full speed and large models in low bit quants.
I care about one question. Does it load, does it run, and what did it actually do? The box is in The AI Hardware I Own: ASUS Ascent GX10, a Mac mini and a MacBook Pro.
The big one: DeepSeek V4.1 Flash at 1.62-bit
DeepSeek V4.1 Flash at 1.62-bit ran locally on my GX10. The quant pack is from Cruz.
A 1.62-bit quant is aggressive. It still loaded and ran on the box.
Small local models I've run
These are the small ones. All ran locally on the GX10.
- Gemma 4 E4B Q4
- Granite 4.2 3B Q4
- Phi-4-mini
- SmolLM3 3B
- Llama 3.2 3B Instruct
- LFM2.5-2.6B Q4
- Nemotron 3.5 Bolt E4B Q4
The small five (Gemma 4 E4B, Granite 4.2 3B, Phi-4-mini, SmolLM3 3B, Llama 3.2 3B Instruct) all ran at Q4.
I'm careful about how I compare small models. When two land close, I say so up front. Neck and neck is neck and neck.
NVIDIA Nemotron 3.5 Lightning NVFP4
Nemotron 3.5 Lightning NVFP4 ran locally on my GX10. I put it head to head with Nemotron 3.5 Bolt E4B Q4. Same box, same task suite. WikiBench scored 92 tasks for Lightning and 93 for Bolt.
Qwen3.8 Flash Next in three quants
One model, three quants. I ran Qwen3.8 Flash Next locally on the GX10 as Cruz's (@ViC305) SAGE EXL3 4.77bpw quant, turboderp's EXL3 3.05bpw quant running on Cruz's TabbyAPI/exllamav3 recipe, and an FP4 build.
This is the kind of test I like. Same model, same tasks, only the quant changes. You see what the quant costs you.
A router in front of two local models
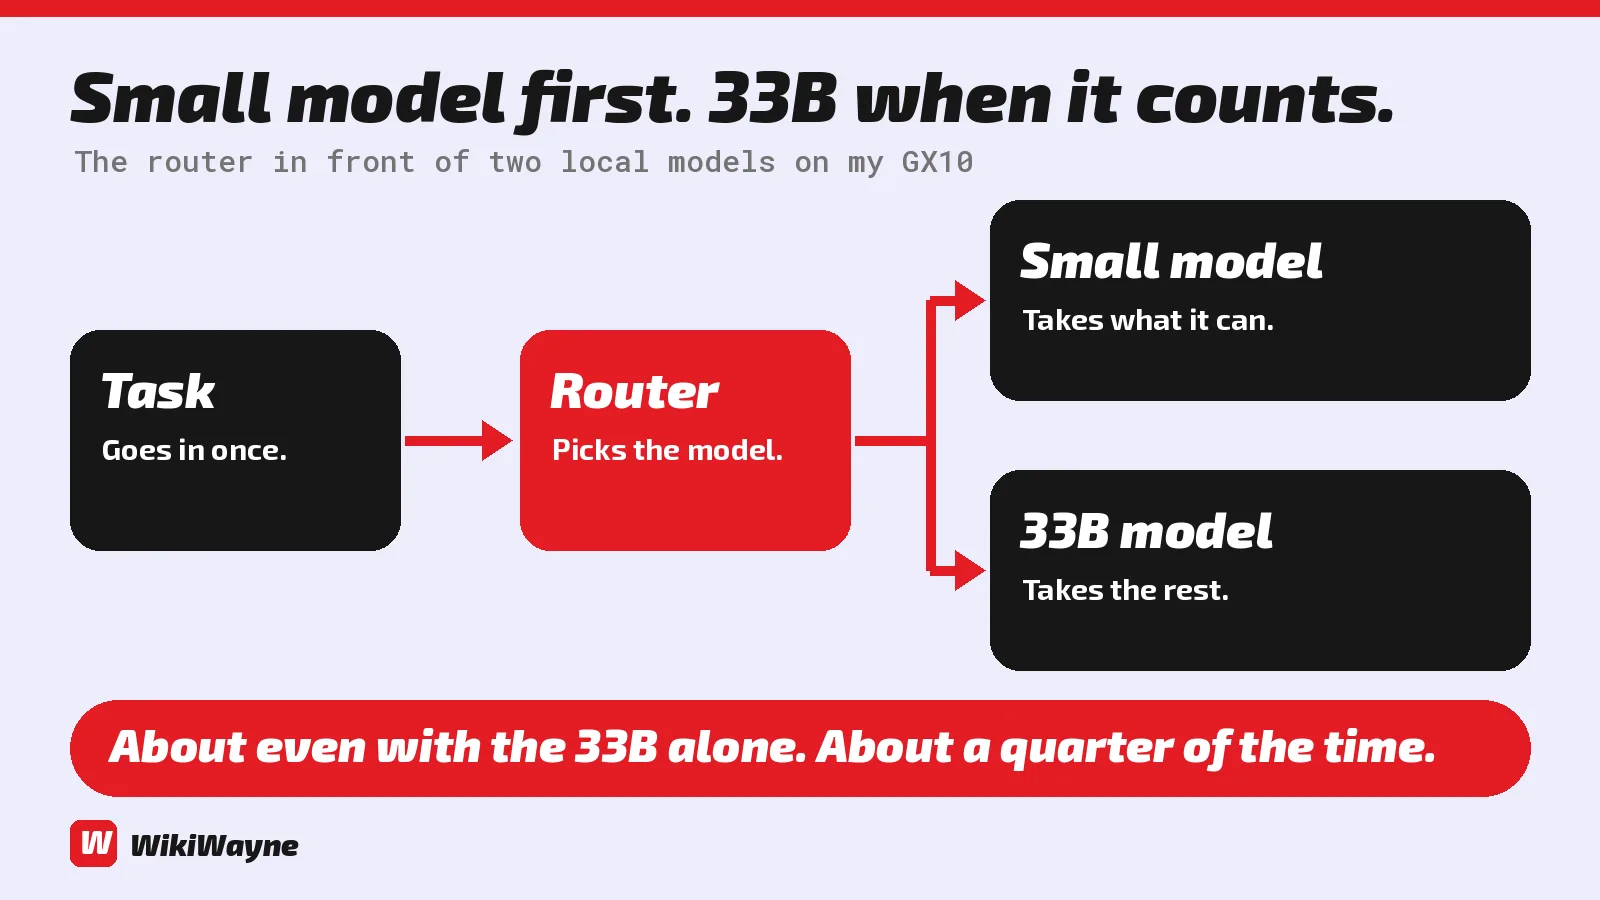
I put a router in front of LFM3-1.7B and Nanbeige4.3-33B (SAGE EXL3 quant by Cruz) on my GX10.
The small model takes what it can. The 33B takes the rest. The combined result landed about even with the 33B alone, in about a quarter of the time.
That's the same idea I use with agents. Cheap model for the grunt work, strong model for the hard part. More in Hermes Agent on My GX10, Over Telegram.
What I leave out
I don't call a model local unless it ran on my box.
I also don't post tokens per second without a run log behind it.
How these feed my rankings
The local runs feed WikiBench. The game gauntlets run mostly on hosted models through Nous Portal and other routes. My favorites from those are in My Model Rankings and Favorites, From Gauntlet Receipts. The bots that run all of it are in My Grok Bot Team Runs My Content, Site and Video Work.
Read the rest of the stack
Affiliate Disclosure: As an Amazon Associate I earn from qualifying purchases. This site contains affiliate links.